I am a PhD student in Computer Science at Berkeley AI Research (BAIR), UC Berkeley, advised by Prof. Kurt Keutzer. My research focuses on efficient machine learning, especially quantization and sparsity, to compress and accelerate language models and video generation models while preserving accuracy and robustness.
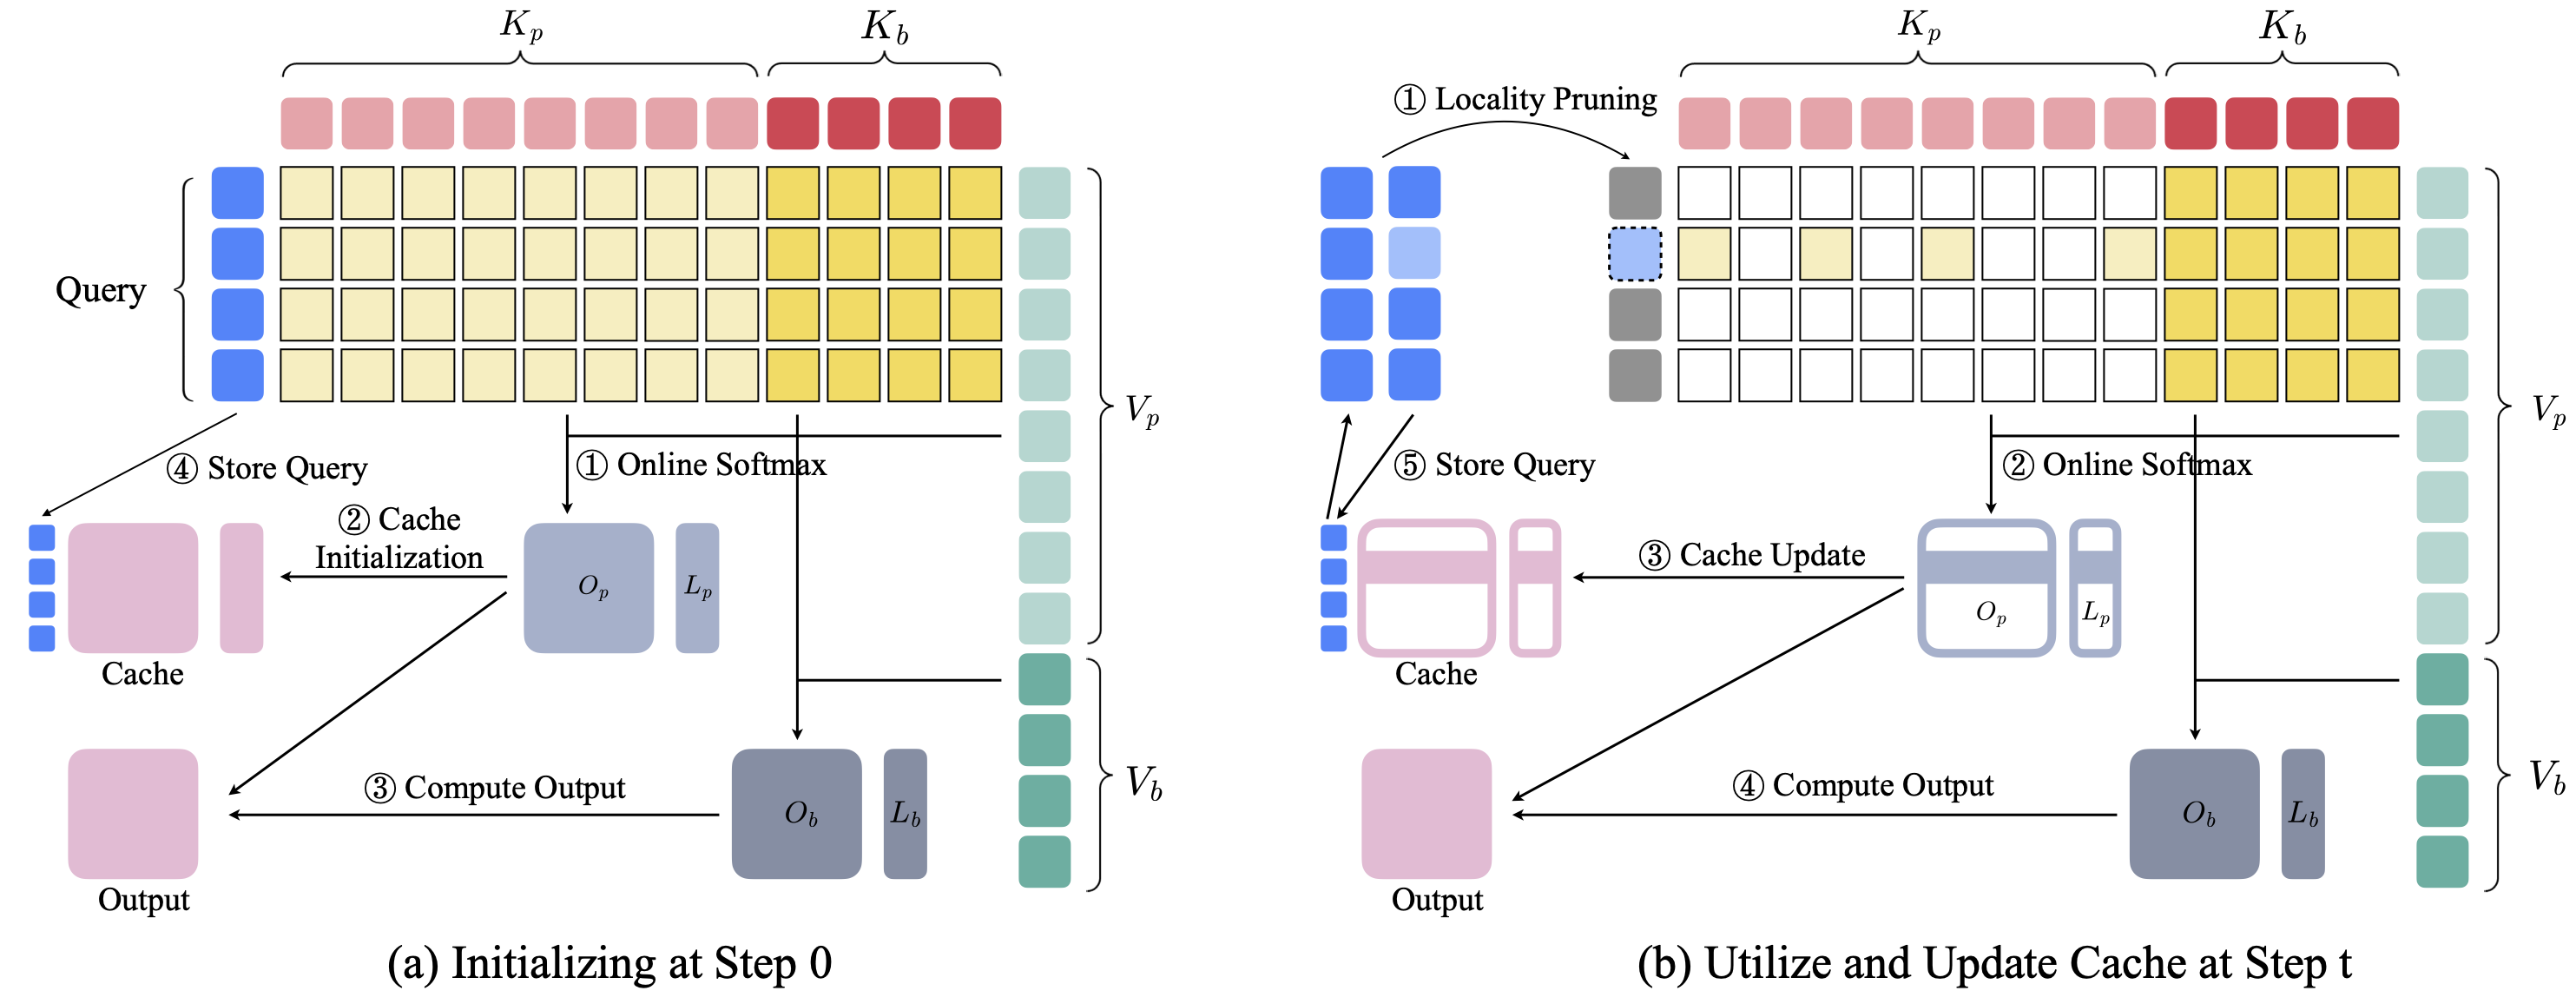
We propose LoSA, a locality-aware sparse attention for block-wise diffusion language models. LoSA reuses cached prefix-attention for stable tokens and applies sparse attention only to active tokens, achieving up to +9 accuracy points at aggressive sparsity, 1.54x lower attention density, and 4.14x attention speedup.
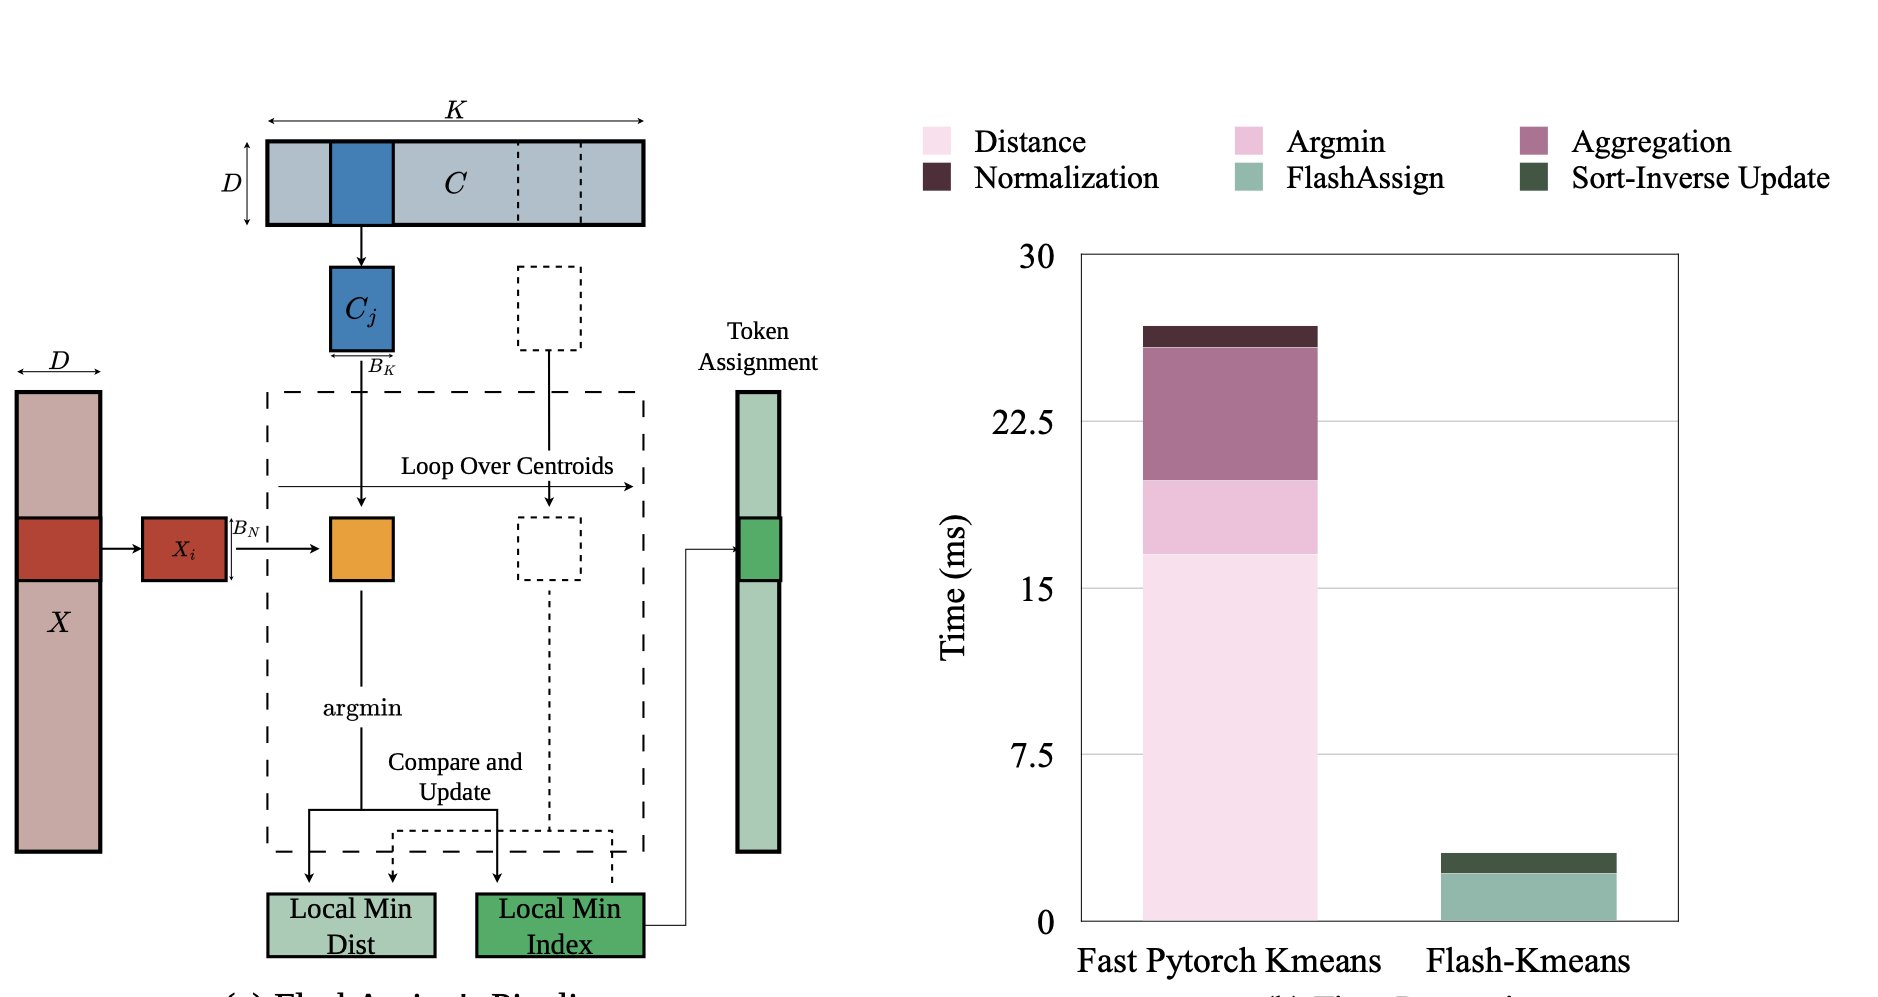
Flash-KMeans: Fast and Memory-Efficient Exact K-Means
We propose Flash-KMeans, an IO-aware and contention-free k-means for modern GPUs. FlashAssign fuses distance computation with online argmin; Sort-Inverse Update transforms atomic scatters into localized reductions. Achieves up to 17.9x end-to-end speedup, 33x over cuML, and 200x+ over FAISS on H200 GPUs.
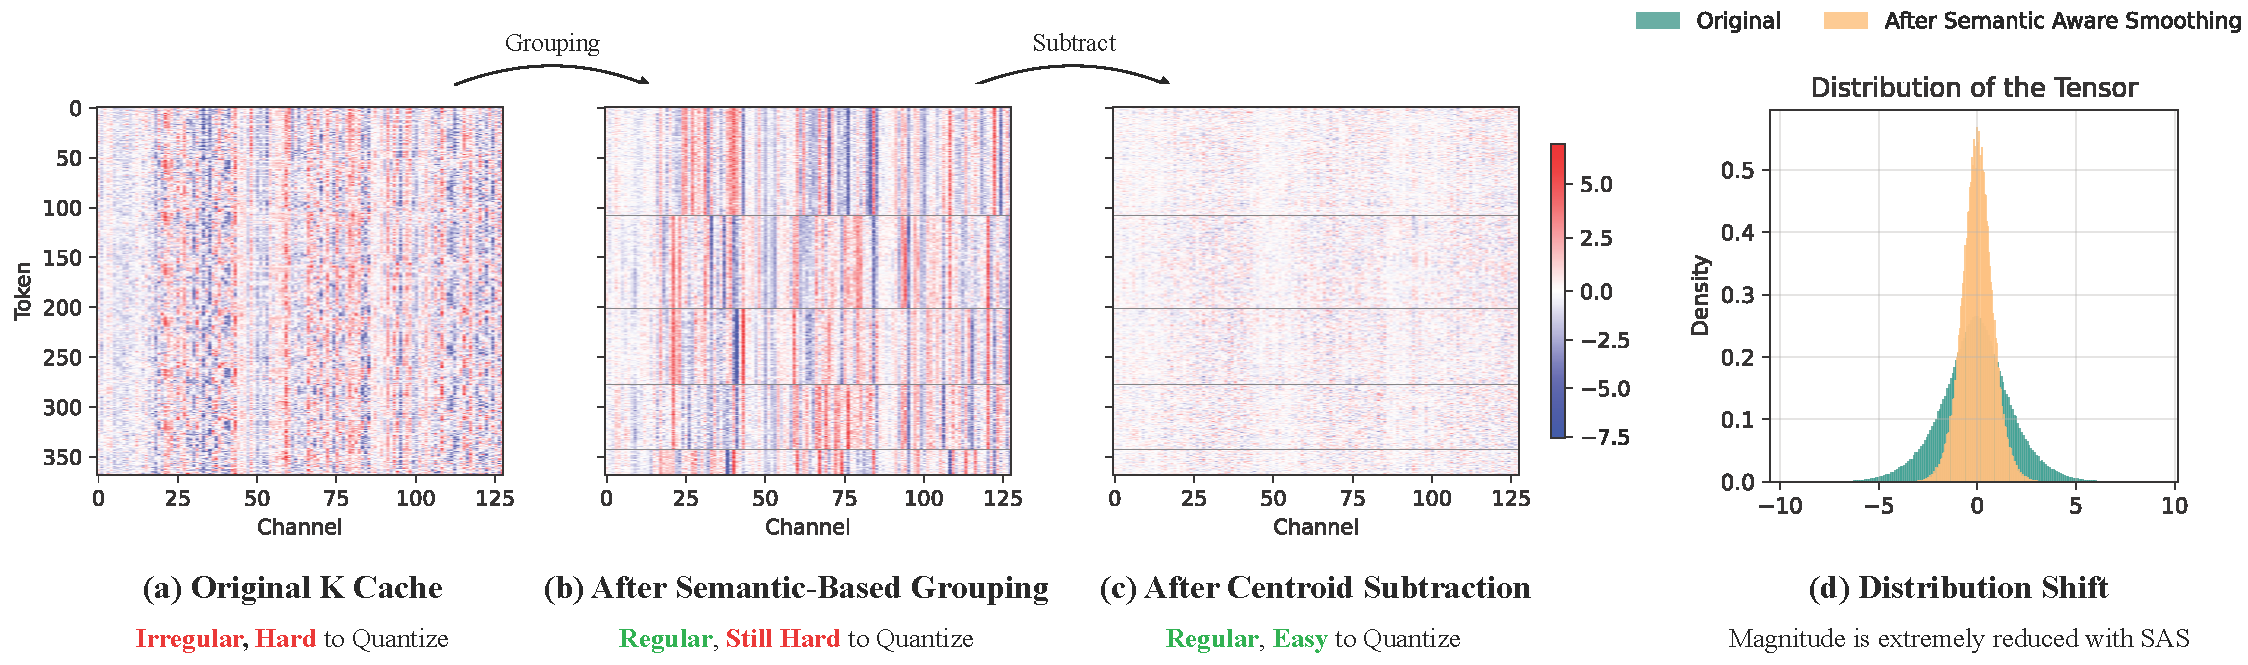
Quant VideoGen: Auto-Regressive Long Video Generation via 2-Bit KV-Cache Quantization
We present Quant VideoGen (QVG), a training-free KV cache quantization framework for autoregressive video diffusion with semantic-aware smoothing and progressive residual quantization. Reduces KV cache memory by up to 7× with under 4% end-to-end latency overhead while improving quality over baselines.
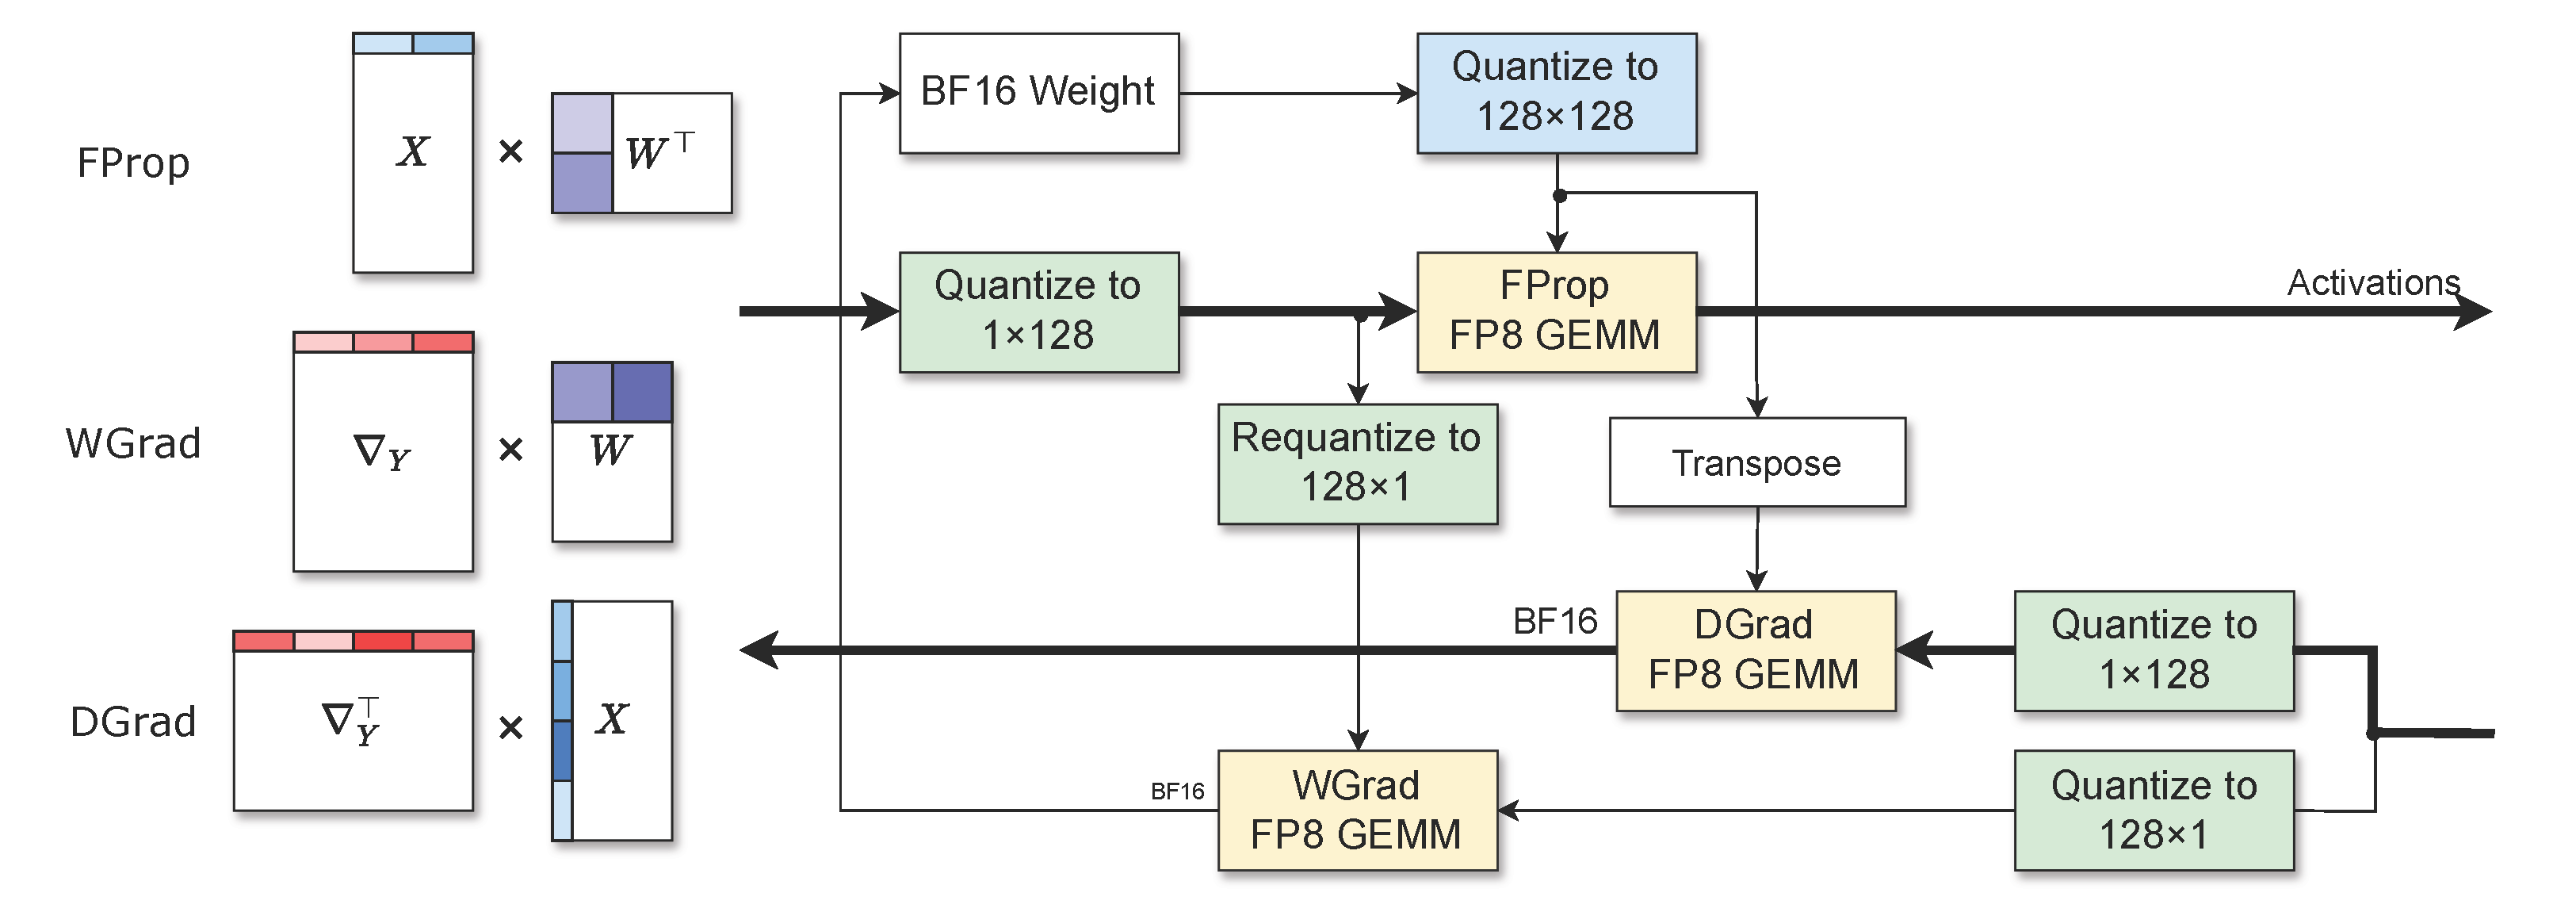
Jet-RL: Enabling On-Policy FP8 Reinforcement Learning with Unified Training and Rollout Precision Flow
We unify FP8 precision across RL training and rollout to avoid off-policy numerical mismatch from BF16-train + FP8-rollout, which can destabilize long-horizon RL. Achieves up to 33% rollout speedup, 41% training speedup, and 16% end-to-end speedup over BF16 with stable convergence.
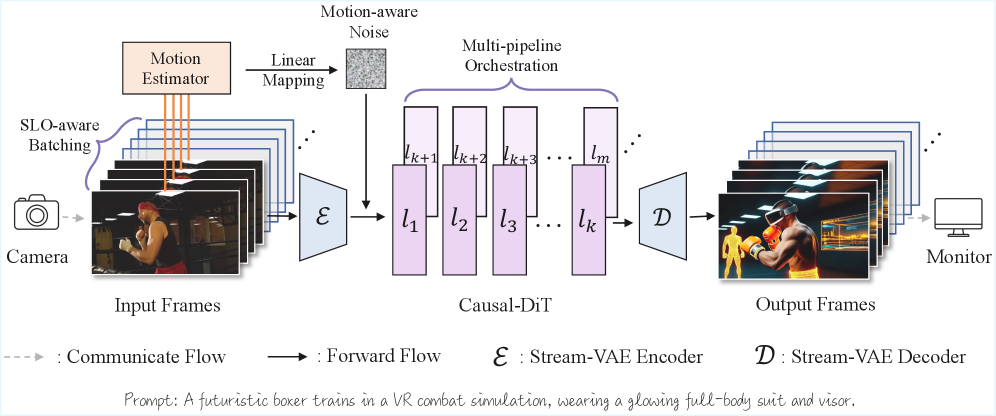
StreamDiffusion V2: A Streaming System for Dynamic and Interactive Video Generation
We present StreamDiffusionV2, a training-free streaming system that adapts video diffusion models for interactive, low-latency live generation. It integrates an SLO-aware batching scheduler, sink-token-guided rolling KV cache, motion-aware noise controller, and scalable pipeline orchestration across denoising steps and network layers. Achieves 0.5s time-to-first-frame and up to 58.28 FPS (14B) / 64.52 FPS (1.3B) on 4xH100 without TensorRT or quantization.
Sparse VideoGen 2: Accelerate Video Generation with Sparse Attention via Semantic-Aware Permutation
We propose a training-free sparse attention framework that uses semantic-aware permutation - clustering and reordering tokens via k-means based on semantic similarity - to achieve a new pareto-frontier in speed-quality tradeoff.
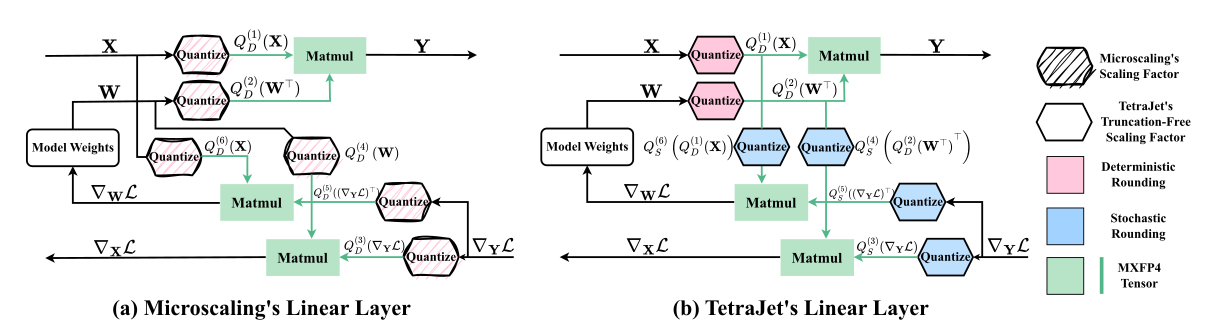
Oscillation-Reduced MXFP4 Training for Vision Transformers
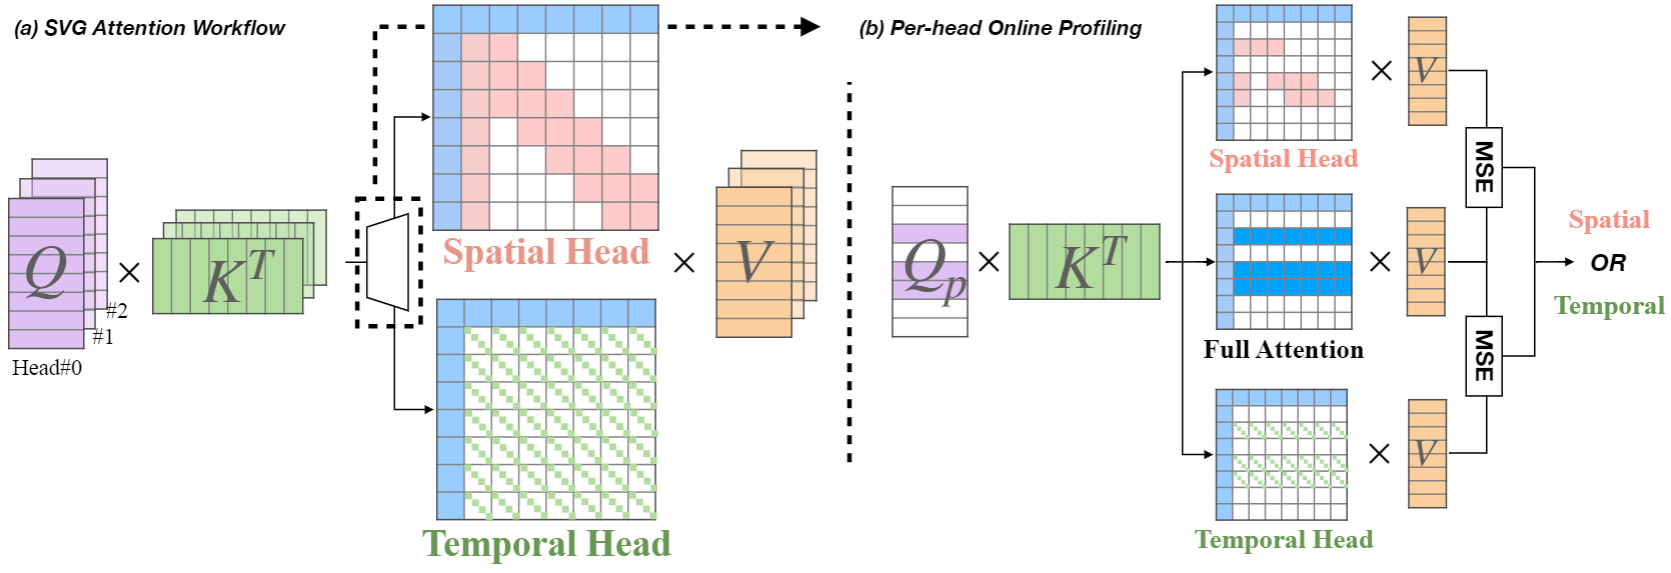
We identify the spatial head and temporal head pattern in attention map and propose to use sparse attention to accelerate. Achieves up to 2.28x and 2.33x end-to-end speedup on CogVideoX-v1.5 and HunyuanVideo.
COAT: Compressing Optimizer states and Activations for Memory-Efficient FP8 Training
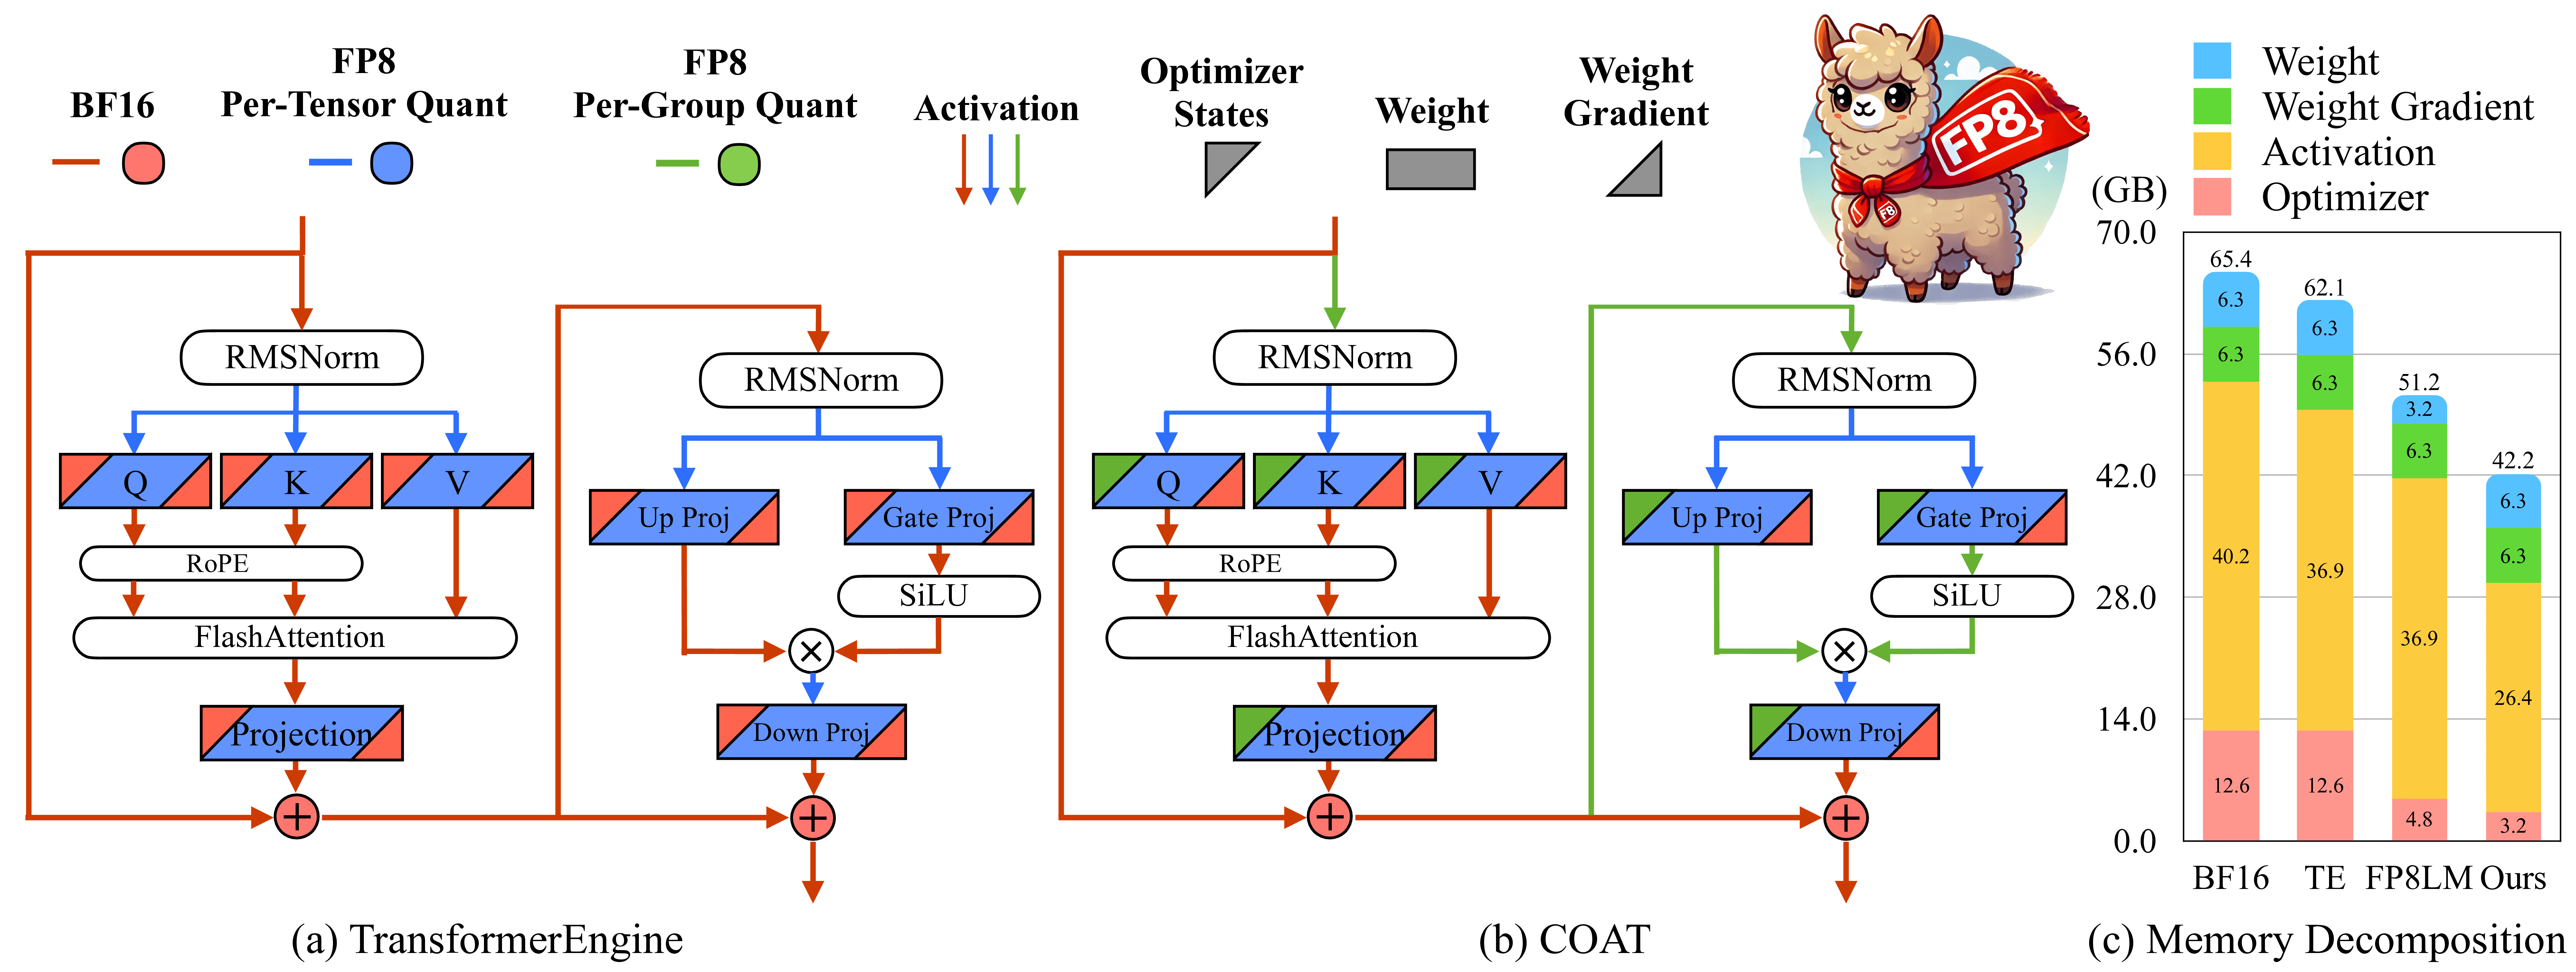
We propose Dynamic range expansion for FP8 optimizer, and propose FP8 precision flow for FP8 activations. Achieve Lossless performance, end-to-End 1.54x memory reduction and 1.43x training speedup over BF16.
Jetfire: Efficient and Accurate Transformer Pretraining with INT8 Data Flow and Per-Block Quantization
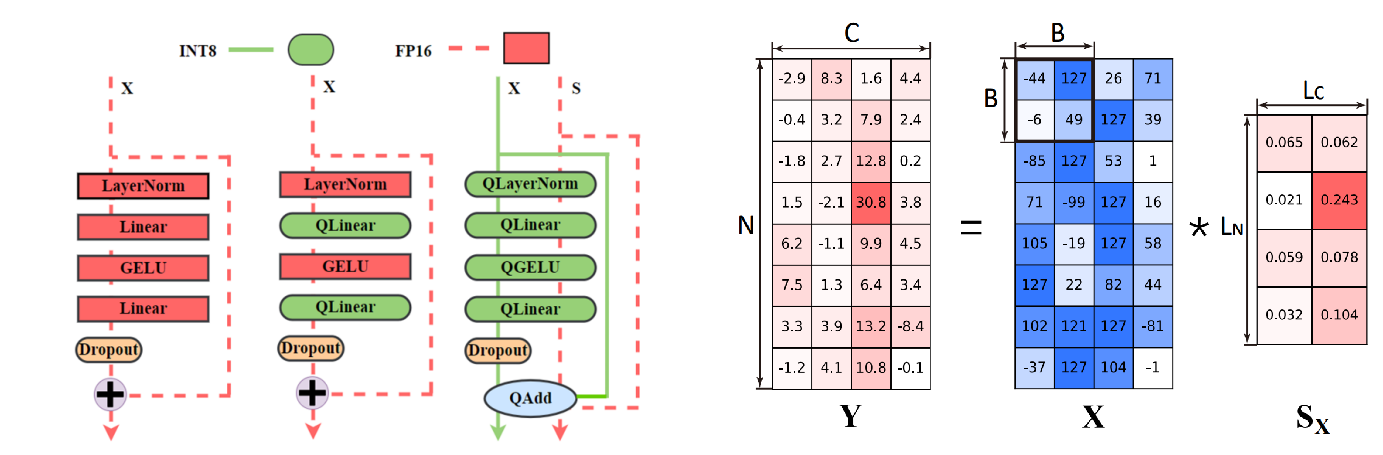
We propose a new method for efficient and accurate transformer pretraining with INT8 data flow and per-block quantization. Demonstrate effectiveness on GPT2-774M model. Achieve End-to-End 1.42x training speedup and 1.49x memory reduction.
Propose Hadamard Quantizer and Leverage Score Sampling to enable INT4 Precision Matmul in training for speedup. Both the forward and backward pass are quantized into INT4 precision for maximized speedup. Outperforms all existing 4-bit training baselines.
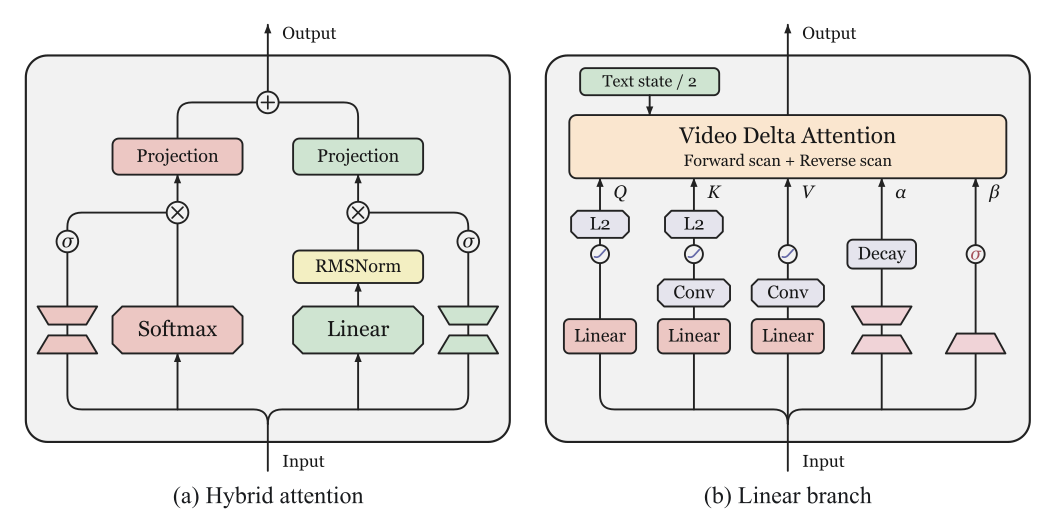
We introduce a video-native hybrid attention architecture that combines local softmax attention with bidirectional linear memory. A frame-wise delta rule preserves long-range context, while staged adaptation retains the pretrained model’s capabilities. With eight-step distillation and optimized kernels, VDN-H3 denoises a 14.3-second, 768p video in 6.7 seconds on eight B200 GPUs.
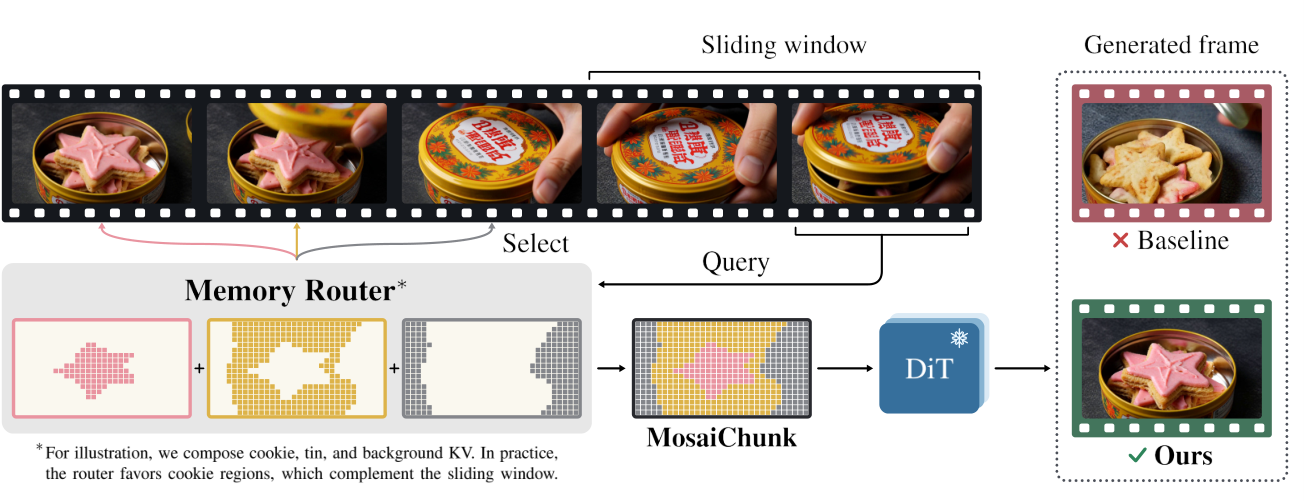
We give autoregressive video models persistent visual memory by composing selected historical KV entries across space and time. A lightweight router learns which details to retrieve while the generator stays frozen. At matched memory budgets, MosaiChunk improves revisit consistency over sliding windows and whole-chunk retrieval, preserving objects and scenes when they reappear in long videos.
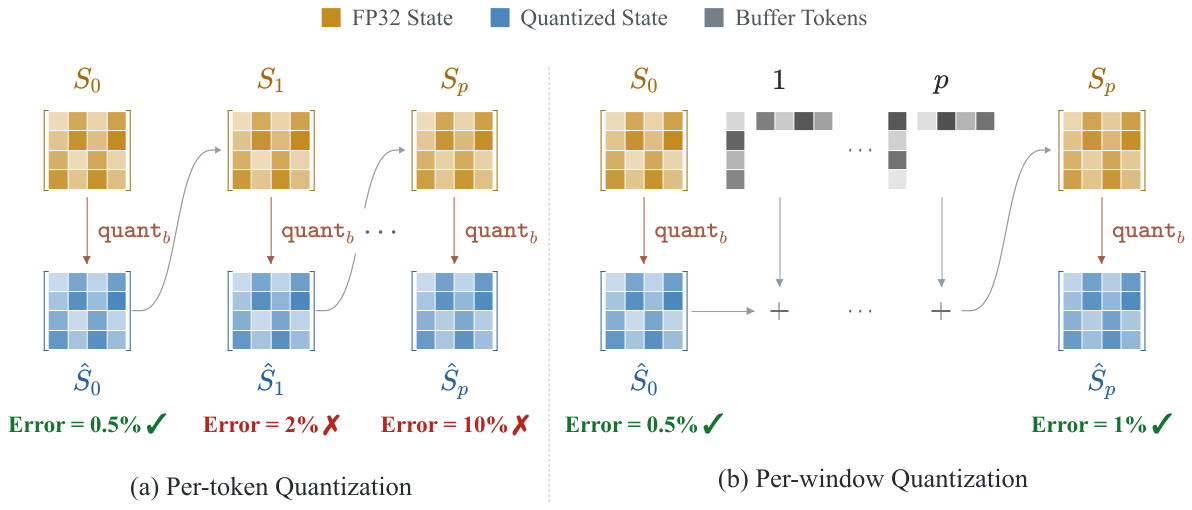
We make recurrent-state quantization accurate for linear-attention LLMs without retraining or calibration data. Per-window quantization limits error accumulation, while high-precision Compensator Tokens and residual smoothing handle outliers. Across Qwen, Kimi, and GLM models, 8-bit states retain near-FP32 quality, with average kernel speedups of 2.05–3.70× and a 1.47× end-to-end inference speedup.
We address KV inflation in block-wise diffusion language models by reusing prefix-attention results for stable tokens and computing sparse attention only for active tokens. This reduces the union of KV pages loaded at each denoising step. LoSA reaches up to 4.14× attention speedup on RTX A6000 GPUs while preserving near-dense accuracy.
We redesign exact k-means around GPU memory traffic and atomic contention. FlashAssign fuses distance computation with online argmin, avoiding the full distance matrix; a sort-inverse update converts scattered atomic writes into localized reductions. On H200 GPUs, Flash-KMeans achieves up to 17.9× end-to-end speedup over the strongest evaluated baselines.
We compress the growing KV cache of autoregressive video diffusion models with a training-free, 2-bit quantization framework. Semantic-aware smoothing exploits spatiotemporal redundancy, and progressive residual quantization preserves fine detail. Across LongCat Video, HY WorldPlay, and Self Forcing, QVG reduces KV-cache memory by up to 7× with less than 4% end-to-end latency overhead.
We identify numerical mismatch between BF16 training and FP8 rollout as a cause of instability in long-horizon reinforcement learning. Jet-RL unifies the FP8 precision flow across both stages to keep optimization stable without inter-step calibration. It delivers up to 33% rollout speedup, 41% training speedup, and 16% end-to-end speedup over BF16.
We build a training-free system for interactive video generation with strict frame deadlines. SLO-aware scheduling, a rolling KV cache, motion-aware noise control, and pipeline parallelism coordinate streaming across GPUs. On four H100s, the system produces its first frame within 0.5 seconds and reaches 58.28 FPS with a 14B model, without TensorRT or quantization.
We cluster and reorder video tokens by semantic similarity so sparse attention can identify important regions accurately and process them as contiguous GPU workloads. Dynamic attention budgets and custom kernels turn this structure into practical acceleration without retraining. SVG2 achieves up to 2.30× speedup on HunyuanVideo and 1.89× on Wan 2.1 while preserving generation quality.
We introduce TetraJet for MXFP4 training and identify weight oscillation around quantization boundaries as a key source of accuracy loss. Truncation-free scaling and double quantization improve numerical accuracy; an EMA quantizer and adaptive ramping optimizer stabilize training. On vision transformers, these techniques reduce accuracy degradation by more than 50% relative to the evaluated baseline.
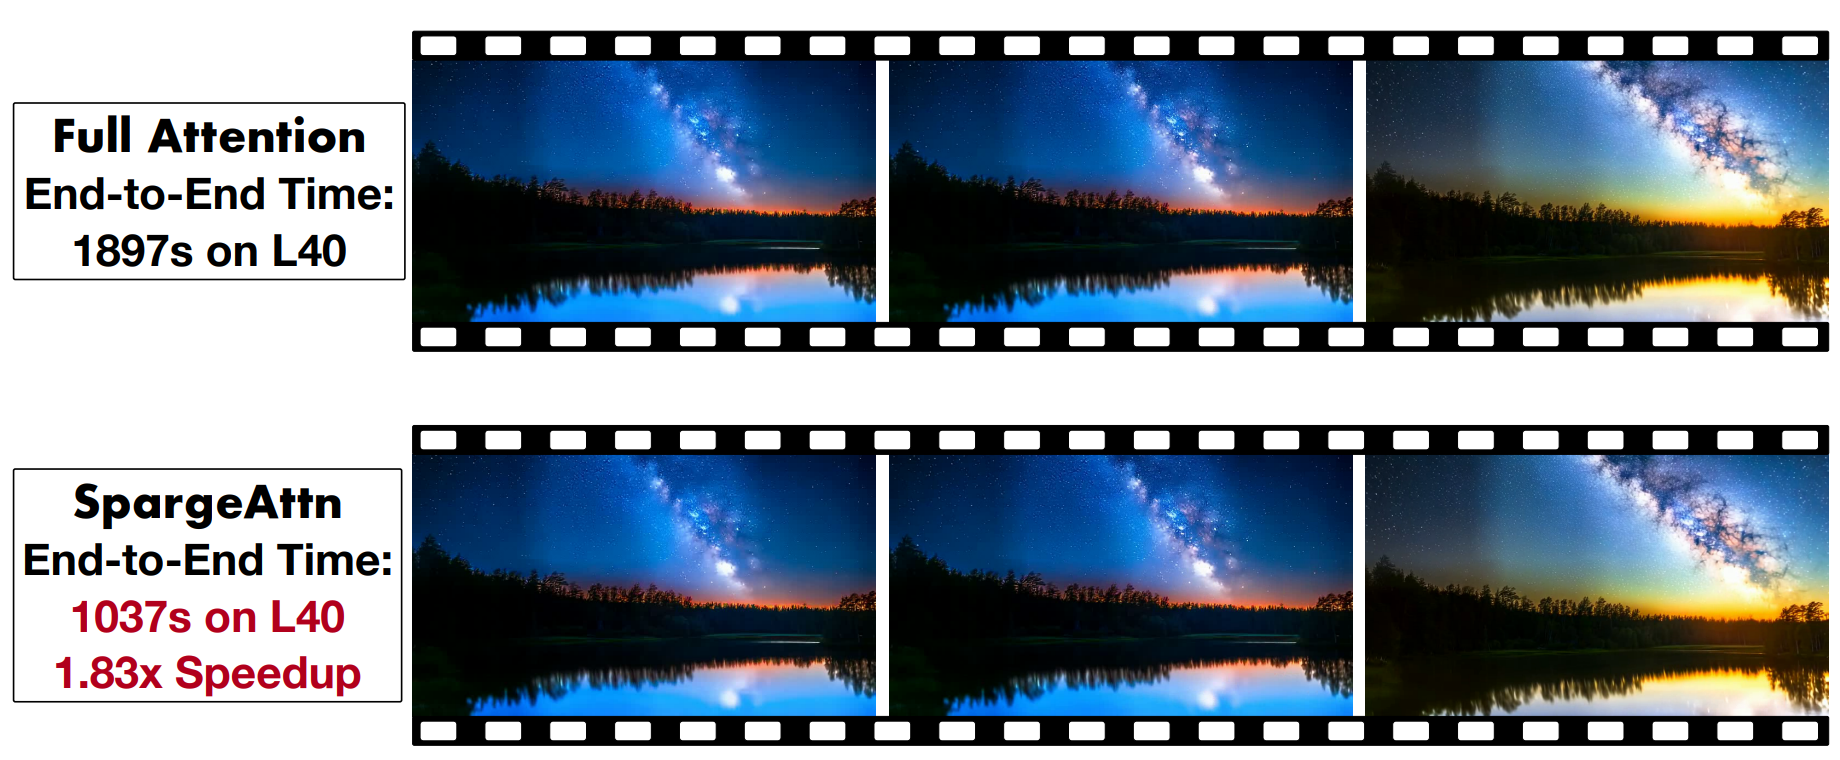
We accelerate attention across language, image, and video models using a training-free combination of sparsity and quantization. A first online filter predicts important attention regions and skips unnecessary matrix multiplications. A second, softmax-aware filter removes additional work with no extra filtering overhead, preserving end-to-end model quality across diverse workloads.
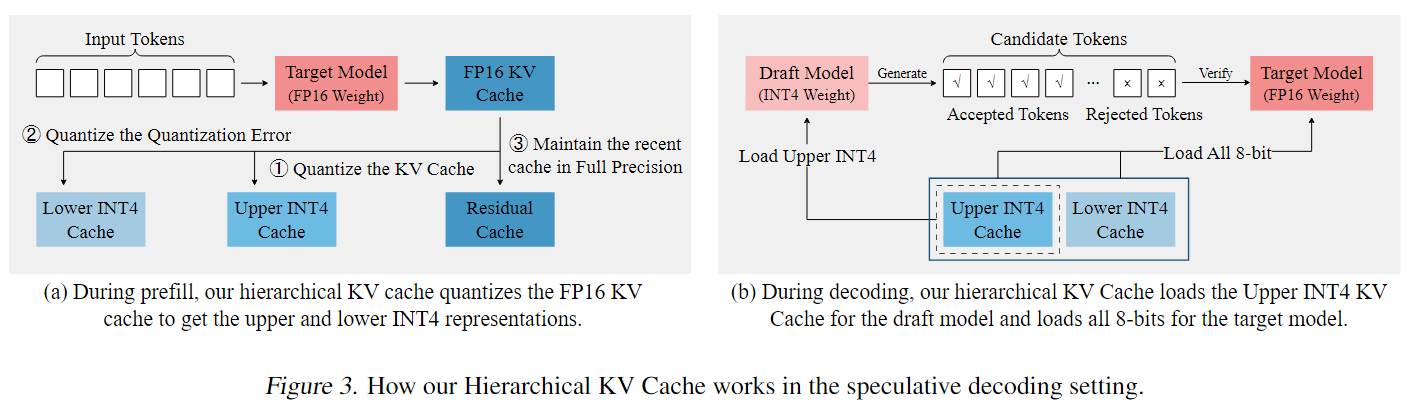
We accelerate long-context generation through self-speculative decoding with 4-bit draft weights and a hierarchical quantized KV cache. The draft shares the target model’s architecture, keeping proposals accurate while reducing memory traffic. QuantSpec maintains acceptance rates above 90%, achieves up to approximately 2.5× end-to-end speedup, and uses about 1.3× less memory than sparse-cache alternatives.
We reveal complementary spatial and temporal patterns in video-transformer attention and select the appropriate sparse computation for each head through online profiling. Hardware-aware tensor layouts and custom kernels make these patterns efficient on GPUs. Without retraining, SVG preserves video quality while reaching 2.28× and 2.33× end-to-end speedup on CogVideoX-v1.5 and HunyuanVideo.
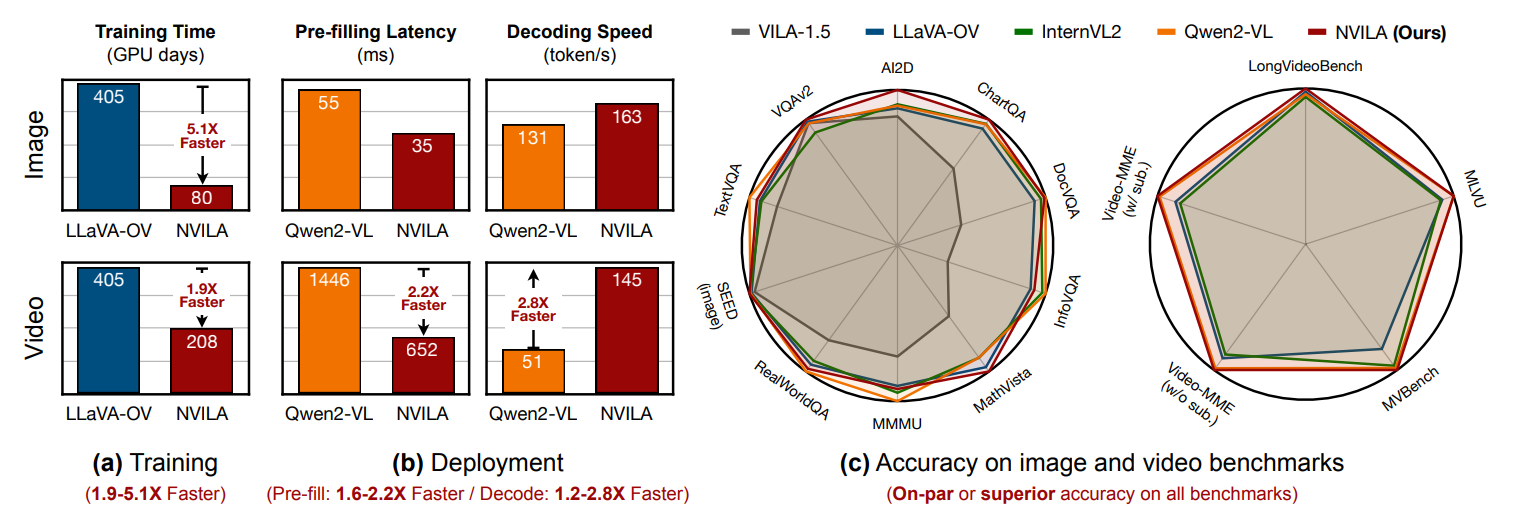
We develop efficient vision-language models with a scale-then-compress design: increase image resolution and video length, then compress visual tokens. Optimizations span training, fine-tuning, and inference while maintaining competitive accuracy on image and video benchmarks. NVILA reduces training cost by 1.9–5.1×, prefill latency by 1.6–2.2×, and decoding latency by 1.2–2.8×.
We reduce the memory footprint of FP8 training beyond matrix multiplication. Dynamic range expansion improves optimizer-state quantization, while mixed-granularity activation quantization reduces saved-activation memory. Across language and vision-language training tasks, COAT provides 1.54× lower end-to-end memory usage and 1.43× training speedup over BF16 with nearly lossless model quality.
We keep transformer computations in an INT8 data flow to reduce repeated quantization and memory transfers. Per-block quantization controls numerical error, enabling pretraining accuracy comparable to FP16. For a standard transformer block, Jetfire achieves 1.42× end-to-end training speedup and 1.49× lower memory usage than the FP16 baseline.
We enable INT4 matrix multiplication in both forward and backward passes on existing GPUs. A Hadamard quantizer suppresses activation outliers; bit splitting and leverage-score sampling preserve sparse gradient information. The method maintains competitive accuracy across language and vision tasks, with linear operators up to 2.2× faster than FP16 and training accelerated by up to 35.1%.